Why upscaling to 4K takes so long
Because Crisp runs every single frame through an upscaling model on its own, and a 4K frame is about 8.3 million pixels, four times a 1080p frame. On my M1 Ultra, a 40-second 1080p phone clip took 3 min 26 s to reach 4K, about five times its own length (Crisp 1.0.1777, 2 November 2026). The cost is per frame, not per file, so trimming before you upscale is the one lever that removes work instead of making each frame cheaper.
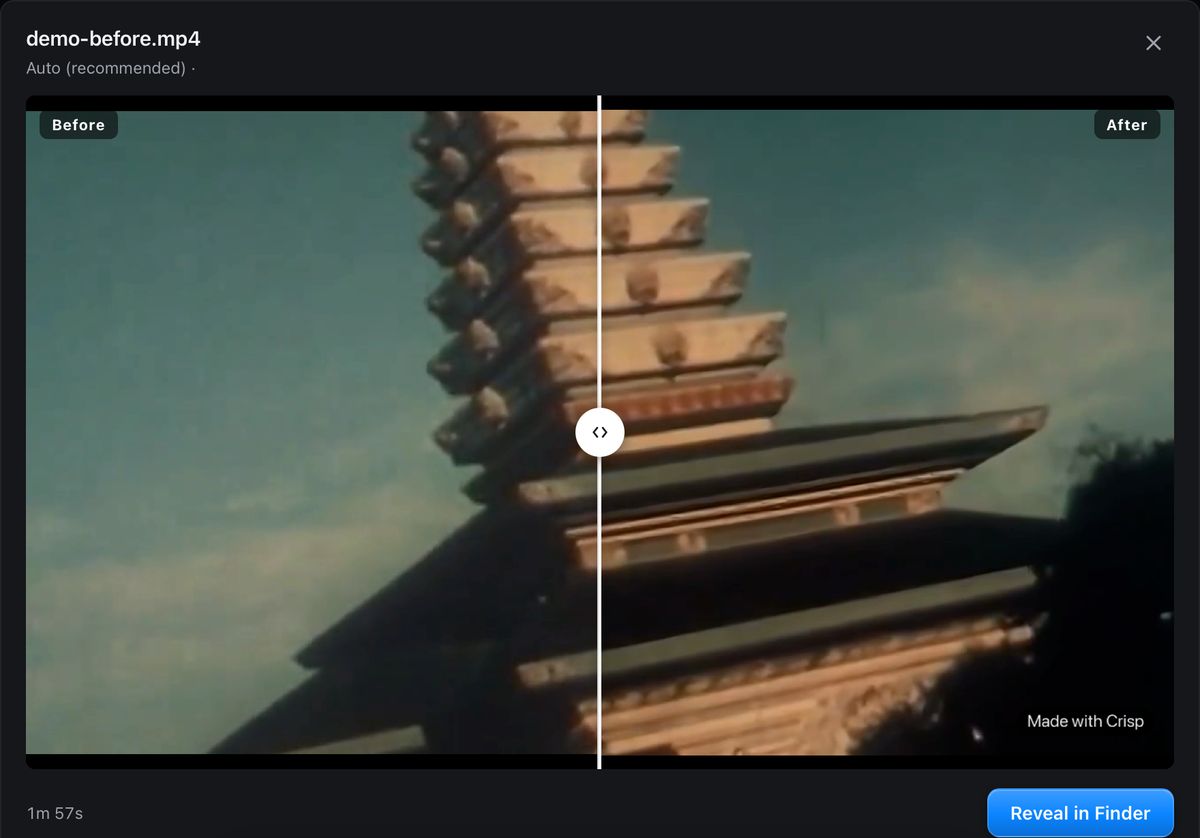
People are often surprised that upscaling a short clip can take longer than the clip itself by a large multiple. It is worth understanding where the time goes, because some of it is avoidable and some of it really is not.
Every frame is a separate job
A normal video export re-encodes frames, which modern hardware does in dedicated silicon at extraordinary speed. AI upscaling is a different kind of pipeline. Inside Crisp a render goes probe → extract → upscale → encode → concat → mux: the extract step decodes your video into numbered still images on disk, and the upscale step runs the model over that folder of frames. The progress bar you watch is the count of output files that exist so far.
So a ten minute clip is not one job. At 30fps it is eighteen thousand of them, each a full network pass over a whole image. The model has no memory of the previous frame and gets no discount for the frame being similar to it.
The arithmetic, and one measured number
A ten minute clip at 30fps is eighteen thousand frames. Longer sources get worse fast: one real render we have on record took a 36.7-minute source and decoded it to 66,120 frames. That figure is just length times frame rate, and it multiplies everything else.
Is the per-frame cost the whole cost, or is there a fixed setup fee a long job would amortise? On Crisp's Max lane we timed three run lengths: 5 frames in 85.3 s, 10 in 206.9 s, 60 in 1348 s. Fit a line through those and the fixed cost comes out negative: the per-frame term explains all of it. We did not record which machine those runs were made on, so read them as a shape rather than a speed to expect. Max is also a far slower engine than the ordinary Enhance path; the point here is the linearity, not the rate.
That is also why this page gives you one measured figure and not a rule. Measured on an M1 Ultra with Crisp 1.0.1469 on 13 October 2026, minutes of processing per minute of video: 5.9 for 1080p at 2×, 5.3 for 720p to 4K on Auto, 10.5 for 1080p with Denoise 0.6, and 5.9 for 720p at 4×. Seconds per frame varies by output resolution and by machine by more than an order of magnitude (Crisp's own estimator says so in its source), so a different Mac will not match those. The Max lane projects from the rate it observes on your own footage instead.
Where the rest of the time goes
Decoding, the colour chain and writing frames out are real costs, though smaller. At 4K the model is producing roughly eight million pixels per frame and the encoder is compressing eight million per frame, four times a 1080p export of the same length. Pixel count scales with area, so doubling each dimension quadruples the work. The most counter-intuitive thing about the maths, and the reason "just a bit bigger" never is.
Memory matters more than people expect. Large frames and large models compete for one pool, and when it is tight the work is broken into tiles and reassembled, costing time and a little quality at the seams. In Crisp that applies to very large frames, past about four megapixels going in: ordinary HD and smaller frames go through the GPU in one piece. For the tiled route Crisp does not guess a tile size: it uses the upscaler's own automatic behaviour unless a measured profile exists for your machine, because a value that helps a 64GB Mac Studio can starve a 16GB Air.
And the bundled networks are natively 2×, 3× and 4× only. Beyond that Crisp composes real passes ( 8× is a 4× pass then a 2× pass) so each pass runs the whole model over every frame again, the second on images the first already enlarged.
A bigger scale factor does not always mean a longer wait
We timed four routes over 60 frames of the same 720p clip, rebuilt two ways: from 320×180 at 4×, and from 640×360 at 2×. Both land back on exactly 1280×720. These seconds are for 60 frames at very small sizes and we have not recorded the machine they were measured on (read the ratios, not the absolute times).
| Route | Seconds (60 frames) | PSNR | VMAF |
|---|---|---|---|
| 4× AI (RealESRGAN_General_x4_v3) | 2.78 | 29.09 | 86.93 |
| 4× lanczos resize | 0.44 | 36.03 | 88.12 |
| 2× AI (2x-ParimgCompact) | 3.89 | 33.35 | 75.59 |
| 2× lanczos resize | 0.44 | 40.77 | 98.99 |
The 4× route finished faster than the 2× route. We are not going to tell you that 4× is quicker than 2×, because this measurement cannot show that. The two runs used different models: Crisp picks the model from the denoise value and the scale together, and it will not run the detail net at 2× or the compact net at 4×, so scale and model cannot be separated without a code change. What the pair does establish is that here the scale factor was not what decided the wall clock: worth knowing, because it is the assumption everyone starts from. The denoise dial is the control that swaps the model, and it is a bigger lever than it looks.
The quality columns are there because "how long" is only half the question. Against a plain lanczos resize the AI route cost six to nine times the wall clock here, and at 2× it also scored 23.4 VMAF points below that resize, at 4× it was within 1.2. Unflattering about our own default, and what the measurement says: the harder the reconstruction, the more the model earns its cost.
What genuinely makes it faster
Trim first. The single biggest lever, and the most ignored. If you only need thirty seconds of a ten minute clip, cutting before upscaling removes 95% of the work. Crisp applies a trim to the source before frames are extracted, so the frames you cut are never decoded and never reach the model.
Pick the target you actually need. 1080p to 4K is four times the output pixels of 1080p to 1440p, and on a phone screen the larger target may be invisible. Crisp's presets clamp toward the size on the label rather than multiplying blindly, so "Enhance → 4K" on a 1080p source writes 3840×2160 and not the 7680×4320 the raw factor would give.
Do not stack lanes you do not need. Smooth motion runs frame interpolation after the upscale, on the already-enlarged frames, so doubling the frame rate means generating roughly as many new 4K frames as you started with: a second model over a bigger picture, on top of the part that was already long.
Let it run unattended. Because everything is on-device there is no per-minute billing and no upload, so a long job overnight costs nothing but electricity. That changes the calculation compared with cloud services, where the incentive is to keep jobs short. You also do not have to wait for the end to judge it: on that 40-second clip, Crisp offered the first finished seconds to watch after 1 min 14 s of the 3 min 26 s render.
What does not help
Closing other applications rarely makes a measurable difference unless you were genuinely short of memory, and a higher bitrate affects file size rather than the inference that dominates the time. Nor does running a cheap job first to "warm things up": the start cost is under a second a job on the Mac we timed. No frame is ever cached, so a second run of the same clip costs the same as the first.
Render time, in detail
Is it normal for a ten minute clip to take over an hour?
At the default settings on a fast Mac, close to it. Measured on an M1 Ultra with Crisp 1.0.1469 on 13 October 2026, a one-minute 1080p clip took 5 minutes 17 seconds to reach 4K. A ten minute clip has ten times the frames and the cost is per frame rather than per file, so expect close to an hour (we timed one minute, not ten). A larger output size or a higher Denoise setting costs more, and there is no shortcut that preserves the quality.
Does a faster Mac help?
It should, because the upscaler runs on your Mac's GPU, so GPU speed is what most of the wall clock is waiting on. Memory matters too: a frame larger than about four megapixels going in (past 1440p) takes a slower route that works in tiles. We have not run the same clip across several Macs, so we cannot honestly give you a ratio between two machines.
Why is the first frame slower than the rest?
Before the first frame comes out, the clip has to be analysed and decoded to frames, and the model has to be loaded and set up for the clip's frame size. On an M1 Ultra the model's part of that was about 0.8 seconds (6 frames took 1.7 seconds, 60 frames took 9.8), and analysing and decoding a 30 second 1080p clip took 19 seconds before the upscaling stage began. After that the per-frame cost settles into a steady rate, so a progress estimate taken from the first few seconds tends to read pessimistically.
Can I use my Mac while it runs?
Yes, though heavy GPU work will compete with the render and slow both. Inside Crisp only one GPU job runs at a time (deliberately, because two simultaneous GPU processes is a crash rather than a slowdown) so clicking Preview during a render waits for it or tells you the app is busy. Because nothing is uploaded, leaving a long job running overnight costs nothing beyond power.